🔍 Read the full analysis: Double The AI Bill For A 5.7% Intelligence Improvement on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
A July 2026 analysis of Anthropic’s Claude Fable 5 reports list prices of $10 per million input tokens and $50 per million output tokens, twice Opus 4.8’s rates. Artificial Analysis scores Fable 5 5.7% higher on its Intelligence Index, but the source review found no controlled human-baseline productivity study and identified one unaudited customer anecdote.
A July 2026 review of Anthropic’s Claude Fable 5 finds the model costs twice as much as Opus 4.8 at list prices, while its score on Artificial Analysis’s Intelligence Index is 5.7% higher. The review says evidence that the higher price translates into enterprise productivity gains remains limited to one unaudited customer account, with no controlled human-baseline study identified.
Anthropic lists Fable 5 at $10 per million input tokens and $50 per million output tokens, according to the company’s launch material and platform pricing documents cited by ThorstenMeyerAI.com. Opus 4.8 is listed at $5 and $25, respectively. The review also places Sonnet 4.6 at about $3 per million input tokens and $15 per million output tokens, making Fable 5 about 3.3 times as expensive by those list rates.
On Artificial Analysis’s Intelligence Index, Fable 5 scored 64.9, compared with 61.4 for Opus 4.8. The review describes that difference as a 5.7% increase. On GDPval-AA, a benchmark for knowledge-work tasks, Fable 5 scored 1,932 Elo against Opus 4.8’s 1,890, a 2.2% difference as presented in the source. A full Intelligence Index run was estimated to cost about $9,940 for Fable 5 and $4,970 for Opus 4.8.
The review’s main qualification concerns productivity, rather than benchmark performance or published prices. It found no controlled productivity study measuring Fable 5 against a human or no-AI baseline. The sole enterprise example it identified was a claim in Anthropic’s launch post, attributed to Stripe: a migration across a 50-million-line Ruby codebase was completed in a day, a task that otherwise would have taken a team more than two months by hand. The review found no methodology, independent audit or replication accompanying that account.
AI Economics · Evidence Review · July 2026
Double The AI Bill For A 5.7% Intelligence Improvement
Claude Fable 5 costs twice as much as Opus 4.8 at list price. Its Intelligence Index score is 5.7% higher, while public evidence connecting that benchmark gain to workplace productivity remains limited.
01 / At a glance
The price is clear. The payoff is not.
A July 2026 review compares Claude Fable 5’s published prices with benchmark results. It finds verifiable pricing and test scores, but much thinner public evidence for enterprise productivity gains.
Premium pricing
Fable 5 is listed at twice Opus 4.8’s input and output rates, and about 3.3 times Sonnet 4.6’s rates.
Modest overall lead
Artificial Analysis reports a 5.7% Intelligence Index difference. GDPval-AA shows a 2.2% difference.
Return unestablished
No controlled productivity study against a human or no-AI baseline was identified in the reviewed public material.
02 / Pricing comparison
Pricing against Opus 4.8
List prices make the premium easy to calculate. Actual costs can differ with caching, batch use, and the mix of input and output tokens.
| Model | Input / 1M | Output / 1M | Relative to Fable 5 |
|---|---|---|---|
| Claude Fable 5 | $10 | $50 | 1.0× |
| Claude Opus 4.8 | $5 | $25 | 0.5× |
| Claude Sonnet 4.6 | ~$3 | ~$15 | ~0.3× |
Usage changes the bill: reported Fable 5 prompt caching is $1 per million tokens; batch rates are $5 input and $25 output. A source scenario estimates $7.70 per million blended tokens using seven cache-hit units, two input units, and one output unit.
03 / What the scores measure
A benchmark lead is not a productivity forecast
The reported differences apply to specific evaluations. They do not predict a matching percentage change in employee output, speed, or labour cost.
Artificial Analysis Intelligence Index
Reported difference: 5.7%. Index scores summarize performance on the benchmark’s tests.
GDPval-AA knowledge-work benchmark
Reported difference: 2.2%. Fable 5 reportedly set records in five of ten sub-benchmarks, with variation by task.
04 / The productivity claim
What the Stripe account says—and leaves open
Anthropic’s launch post attributed one customer example to Stripe. The review found no methodology, independent audit, or replication alongside the account.
Migration across a 50-million-line Ruby codebase.
Completed in one day, according to the launch post.
Would otherwise have taken a team more than two months by hand.
Task scope, completion criteria, supervision, and an independent comparison.
“The economics are fully documented. The productivity story is not.”
ThorstenMeyerAI.com · Review summary
05 / Reading the evidence
What the evidence cannot show
The review describes the public material it examined; it does not establish that Anthropic or its customers have no private productivity research. It reports that no controlled, independently audited Fable 5 study was available in those sources.
The Stripe account does not provide enough detail to assess the result as a general productivity measure. Readers cannot see how the task was scoped, how completion was defined, how much human supervision was involved, or how the two-month estimate was calculated.
Benchmark scores have limits too. The 5.7% and 2.2% differences apply to their respective evaluations. Task-level results vary, and neither figure predicts workplace output. Effective costs also vary with token use and caching.
06 / A buyer’s test
How buyers can test the premium
For teams considering Fable 5, the practical question is whether it performs better on their own work enough to justify the added cost.
Use representative tasks
Compare Fable 5 with Opus 4.8 on the same real tasks. Track quality, completion, token use, caching, human review, and total cost.
Measure outcomes clearly
Useful public studies would define participants and tasks, set a human or no-AI baseline, explain the productivity measure, and include independent review or replication.
07 / Key questions
What buyers should know
How much does Claude Fable 5 cost?
The cited list rates are $10 per million input tokens and $50 per million output tokens. The review also reports lower prompt-caching and batch rates.
How does it compare with Opus 4.8?
Fable 5 is listed at twice Opus 4.8’s input and output rates. Its Intelligence Index score is 64.9 versus 61.4, a reported 5.7% difference.
Does 5.7% mean 5.7% higher workplace productivity?
No. It is the reported difference on the Intelligence Index. The review identified no controlled productivity study against a human or no-AI baseline.
Is the productivity claim disproven?
No. The review says the public evidence is limited; it does not rule out private research or gains on particular tasks.
The Cost of Proving Productivity
For organisations choosing a model for a defined task, the figures present a practical purchasing question: whether Fable 5’s performance on their own work is worth its twofold list-price premium over Opus 4.8. The reported overall benchmark gap does not establish that the more expensive model will deliver a corresponding improvement in output, speed or labour costs in a particular workplace.
The distinction matters for budget decisions. Benchmark scores measure performance on specified tests; productivity studies would need to show how people and teams perform with the model in real workflows, using clear comparison methods. The review reports that this kind of human-baseline evidence is absent for Fable 5 in the public material it examined. That does not show the model cannot improve productivity. It means buyers should treat broad productivity claims as unverified unless they are supported by evidence relevant to their own tasks.
Results may also vary across workloads. The source says Fable 5 set records in five of ten sub-benchmarks, with some task-level gains larger than its overall score difference. That makes a single blended score an incomplete guide: a buyer’s decision depends on whether the model’s stronger areas match the work being purchased.
Products Worth Considering

Bose QuietComfort Ultra Headphones (2nd Gen), Wireless Noise-Cancelling Over-Ear Headphones with Spatial Audio, Driftwood Sand
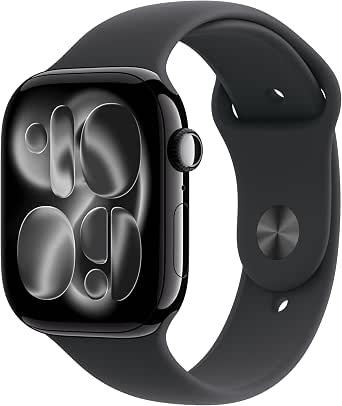
Apple Watch Series 11 GPS + Cellular, 46mm Jet Black Aluminum Case with Black Sport Band (M/L)

Amazon Kindle Scribe Colorsoft 64GB with 11-Inch Color Display and Premium Pen, Graphite
As an affiliate, we earn on qualifying purchases.
Pricing Against Opus 4.8
The review draws a line between data it says can be checked in primary sources and claims that rest on customer testimony. It cites Anthropic’s launch post, platform pricing documents and product page for Fable 5’s list prices, and Artificial Analysis for the benchmark comparisons. It also says the pricing figures are consistent with reporting by outlets and services including Forbes, TechCrunch, Vellum and Finout.
List prices are not the only possible cost. The source says Fable 5 has a prompt-caching rate of $1 per million tokens, a 90% discount from its listed input rate, and batch pricing of $5 per million input tokens and $25 per million output tokens. It estimates a blended price of $7.70 per million tokens under an assumed mix of seven cache-hit units, two input units and one output unit. That is a scenario calculation, not a universal rate; actual costs depend on usage patterns.
The source also says Fable 5 and Mythos 5 use the same underlying weights and have identical prices, while differing in safeguards. It dates Fable 5’s announcement to June 9, 2026, and gives general availability as around July 1. Those dates and product details are reported by the source material.
“The economics are fully documented. The productivity story is not.”
— ThorstenMeyerAI.com, summarising the review’s finding
What the Evidence Cannot Show
The review’s findings describe the public evidence it examined, not every private evaluation that Anthropic or its customers may have conducted. It does not establish that no internal or confidential productivity research exists. It reports that no controlled, independently audited Fable 5 productivity study was available in the reviewed sources.
The Stripe account is also not an independently measured comparison. The source provides the claimed codebase size and time contrast, but does not give details such as the task’s scope, how completion was defined, the amount of human supervision, or how the estimate of two months was calculated. Without those details, readers cannot assess the result as a general productivity measure or compare it reliably with other teams’ work.
Benchmark performance has limits as well. The reported 5.7% Intelligence Index difference and 2.2% GDPval-AA difference apply to those specific evaluations. They do not predict a percentage change in employee output, and the source notes that results differ across sub-benchmarks. The review’s cost estimate also depends on its stated token mix; an organisation with a different balance of cached prompts, input and output would face a different effective rate.
The source does not identify a forthcoming independent productivity study or a confirmed date for one. For now, organisations considering Fable 5 can compare it with Opus 4.8 on representative tasks and record both quality and cost. Such an evaluation would need to account for token use, caching, human review and whether work is completed correctly—not just how quickly the model produces an answer.
Further public evidence would clarify whether Fable 5’s benchmark advantages yield measurable gains in particular workplaces. Useful evidence would specify the tasks and participants, define a human or no-AI comparison, disclose how productivity was measured and provide independent review or replication. Until then, the price and benchmark comparisons are documented in the cited sources, while a general enterprise productivity return remains unestablished.
Key Questions
How much does Claude Fable 5 cost?
According to pricing documents cited by ThorstenMeyerAI.com, Fable 5 costs $10 per million input tokens and $50 per million output tokens at list price. The source also reports discounted rates for prompt caching and batch use.
How does Fable 5 compare with Opus 4.8?
The source lists Fable 5 at twice Opus 4.8’s input and output rates. Artificial Analysis scores Fable 5 at 64.9 on its Intelligence Index versus 61.4 for Opus 4.8, a reported 5.7% difference.
Does the 5.7% score difference mean 5.7% higher workplace productivity?
No. The 5.7% figure refers to the Intelligence Index benchmark comparison. The review found no controlled Fable 5 study establishing a matching productivity gain in enterprise work.
What is the evidence behind the Stripe productivity example?
Anthropic’s launch post attributes to Stripe a claim that Fable 5 completed a migration in a 50-million-line Ruby codebase in one day, compared with more than two months of manual work by a team. The review says the public account has no accompanying methodology, independent audit or replication.
When did Fable 5 become available?
The source dates the announcement to June 9, 2026, and describes general availability as expected around July 1, 2026. The supplied material does not provide a later confirmation of the availability date.
Source: ThorstenMeyerAI.com